Prompt Caching Basics
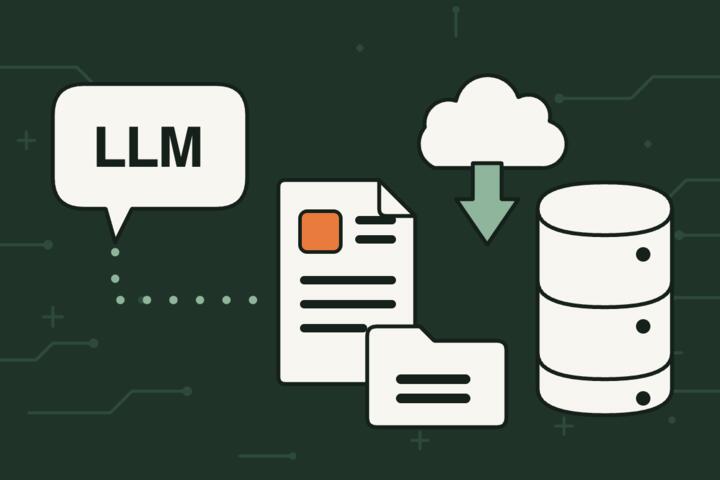
Prompt caching is a mechanism that reuses computation for repeated prompt content so an AI model does not reprocess the same text from scratch each time. In practice, a client sends a prompt that contains both stable parts (instructions, system context, templates) and variable parts (user question, numbers, names). When the stable parts match a prior request closely enough, the service can reuse cached internal states and spend fewer tokens on the “prompt side” of the request.
Most caching systems work at the level of the prompt prefix or a normalized representation of it, not at the level of “meaning.” That distinction matters because small formatting changes can prevent a cache hit even when the intent stays the same. I’ve seen this in tool logs where a single extra space or a different JSON key order changes the cache key, and the request falls back to full processing.
Cost reductions come from fewer prompt tokens being processed, plus lower latency for the prompt portion. The exact savings depend on the provider’s pricing model and how they bill cached versus uncached tokens, which varies by service and plan. Some platforms also charge for caching operations or storage, so you need to measure on your own traffic rather than assume every cache hit reduces the bill linearly.
Where Costs Spike
People often expect caching to reduce costs whenever they “repeat a prompt,” then get surprised when the cache hit rate stays low. The usual cause is that the prompt changes in ways that look minor to humans but matter to the cache key: whitespace, punctuation, ordering of fields, different tool schemas, or different system instructions per request.
Another common pain point is hidden prompt growth. A workflow that appends conversation history, retrieved documents, or tool outputs can create a long prompt where only a small prefix stays stable. If the stable prefix is short, caching saves less than expected because the model still must process the variable tail.
Caching also depends on supporting technologies. A typical stack includes: an API gateway that computes cache keys, a model-serving layer that stores and retrieves cached states, and a client-side prompt builder that keeps stable content consistent. If any layer normalizes text differently between requests, cache reuse breaks. Tooling versions can matter too; for example, a client library update (say, from v1.18 to v1.19) might change how it serializes messages.
Finally, caching can conflict with privacy and compliance goals. If you cache prompts that include personal data, you must understand retention, access controls, and whether cached content can be reused across tenants. Many providers restrict cache scope, but the exact guarantees depend on the service terms and configuration.
Solutions And Advice
Design Stable Prompt Prefixes
Start by separating your prompt into stable and variable segments. Keep the stable segment identical across requests: system instructions, formatting rules, and tool schemas. For variable content, place it after the stable prefix so cache hits can occur before the variable tail forces new computation.
Use deterministic formatting. If you send JSON, keep key order consistent and avoid optional fields that appear and disappear. When you must include dynamic values, prefer placeholders in the stable portion and fill them after the cached prefix. This approach often raises cache hit rate more than any “prompt engineering” trick, because caching cares about exact or near-exact matches.
Track cache hit rate and prompt length together. If your stable prefix is 200 tokens but your prompt is 2,000 tokens, you may still see only modest savings. In one anonymized support workflow, moving a long policy block into a fixed prefix raised hit rate from roughly 20% to around 70%, while total prompt tokens stayed similar; the bill dropped because the prompt-side compute shrank.
Measure Savings With Real Logs
Measure on a slice of traffic that resembles production. Capture per-request metrics: total tokens, prompt tokens, completion tokens, latency, and any “cache hit” indicator exposed by the provider. If the provider does not expose cache hit rate, you can infer it by comparing prompt-token billing patterns across repeated requests.
Run an A/B test by routing a small percentage of requests through the cached prompt builder while keeping everything else constant. Use a fixed time window so model versions and retrieval results do not drift. I’ve seen teams test on a single day and then miss that their retrieval system changed ranking, which altered the prompt tail and reduced cache reuse.
Expect diminishing returns. As hit rate approaches 100%, additional savings become limited by the variable portion and by any minimum billing for prompt processing. Your goal is not perfect reuse; it’s a favorable ratio of cached prompt tokens to total prompt tokens.
Control History And Retrieval
Conversation history is a frequent cache killer. If you append the entire chat transcript every time, the prompt prefix changes continuously. A practical pattern is to summarize older turns into a fixed-length “memory” block and keep that summary stable until it needs refresh. Summaries still change occasionally, but they change less often than raw transcripts.
Retrieval-augmented generation (RAG) can also reduce cache hits because retrieved documents vary. If your retrieval results change, the prompt tail changes and may shift the effective cached prefix boundary. You can mitigate this by caching the retrieval outputs for a short time window, or by structuring prompts so the retrieved content sits after a stable instruction prefix.
Be careful with stale retrieval. If you cache retrieved documents for too long, answers can lag behind policy updates. A short TTL (time-to-live) aligned with your document update cadence often works better than a long cache that quietly drifts.
Handle Privacy And Retention
Review provider documentation and contract terms for caching scope, retention duration, and cross-tenant isolation. Some services treat cached prompt states as internal artifacts with restricted access; others may log metadata that can still be sensitive. If your prompts include health data, financial identifiers, or other regulated content, confirm how caching interacts with your compliance obligations.
Use redaction before caching. Replace personal identifiers with stable pseudonyms that do not reveal identity. Keep the mapping in your own system, not in the cached prompt. This reduces the risk that cached artifacts contain direct identifiers.
Set conservative defaults. If you cannot confirm retention and isolation guarantees, disable caching for prompts that contain sensitive data and enable it only for low-risk templates.
Case Examples
Customer Support Template
A support team used an AI assistant to draft replies. The stable portion included: a system instruction block, brand voice rules, and a tool schema for checking order status. The variable portion included the customer’s issue text and order identifiers. After they standardized whitespace and kept the tool schema identical across releases, cache hit rate rose and the prompt-token portion of the bill dropped.
They still saw variability because the customer issue text changed each request, and because order-status tool outputs differed. The cost reduction came from reusing the stable instruction prefix, not from reusing the entire prompt.
Monthly Report Generation
A small analytics group generated monthly summaries using a long prompt template with definitions and formatting rules. They initially appended the full prior month’s raw notes each run, which prevented reuse. They switched to a two-step workflow: first, summarize prior notes into a fixed-length “context” block; second, generate the report using that context plus the current month’s numbers.
On the report-generation step, the stable prefix stayed constant across runs, so caching helped. The variable tail still included the current month’s numbers, so savings were partial rather than dramatic.
Cache Hit Checklist
| Check | What To Look For | Why It Matters | Action |
|---|---|---|---|
| Stable Prefix | System rules and schemas match byte-for-byte | Cache keys often depend on exact or normalized text | Freeze templates; avoid optional fields |
| Deterministic Formatting | Consistent whitespace and JSON key order | Small diffs can break cache hits | Use a canonical serializer |
| History Control | Transcript growth does not shift the prefix | Long, changing history reduces reuse | Summarize or truncate with a fixed policy |
| Retrieval Placement | Retrieved text sits after stable instructions | Variable documents limit cached prefix length | Cache retrieval outputs with a short TTL |
| Privacy Scope | Retention and isolation are confirmed in terms | Cached artifacts can contain sensitive content | Redact identifiers; disable for high-risk prompts |
Step-by-step checklist for a quick test: (1) Freeze your system prompt and tool schema, (2) send the same prompt twice with only the variable fields changed, (3) compare prompt-token billing and latency, (4) repeat across 20–50 requests to smooth out noise, (5) fix formatting differences until the cache hit rate stabilizes, and (6) re-run the test after any client library upgrade.
Common Mistakes
Teams often treat caching as a “semantic” feature and expect the model to recognize that two prompts mean the same thing. Cache keys usually depend on text identity or a normalized representation, so two prompts that look equivalent to a human can map to different cache entries.
Another mistake is mixing multiple prompt templates under one code path. If the stable prefix differs between templates, the system creates separate cache entries and the hit rate drops. A simple fix is to version templates and route requests to the matching template version.
Some teams measure savings using only total tokens. Prompt caching changes the prompt-side compute more than the completion-side tokens, so you need prompt-token metrics to see the effect. If you only track completion tokens, you can miss the cost reduction while the bill still changes.
Finally, people sometimes cache prompts that contain sensitive identifiers without checking retention and isolation. Even if the model never “remembers” the content in a human sense, cached artifacts can still be stored and accessed according to provider rules. That mismatch between intuition and system behavior causes avoidable risk.
FAQ
Does Prompt Caching Reduce Output Tokens
Prompt caching mainly reduces work on the prompt side by reusing previously computed prompt states. Output length still depends on your generation settings and the model’s behavior, so completion tokens usually do not shrink just because caching is enabled.
What Causes Cache Misses
Cache misses commonly come from changes in the stable prompt prefix, including whitespace differences, different system instructions, altered tool schemas, or different serialization of structured fields. Retrieval results and appended history also shift the prompt content and reduce the portion that can match a prior cached entry.
How Do I Measure Cost Savings
Compare prompt-token billing and latency for repeated requests that share the same stable prefix. Use a controlled test window and track cache hit indicators if the provider exposes them; otherwise, infer savings from prompt-token charges rather than total tokens alone.
Can Caching Break Compliance Requirements
Caching can affect how prompt content is stored and retained, so compliance depends on provider terms and your configuration. For regulated data, confirm retention duration, cross-tenant isolation, and logging practices, then redact identifiers before caching when needed.
Should I Enable Caching For All Prompts
Enable caching for low-risk templates and stable instructions where you can confirm retention and isolation. Disable caching for prompts that contain sensitive personal or regulated data if you cannot verify the caching scope and retention behavior.
Author's Insight
Prompt caching behaves like a memoization layer for prompt prefixes, not like a guarantee that “similar prompts” will reuse computation. The biggest practical lever is prompt determinism: keeping system instructions, schemas, and formatting stable across requests. Cost savings show up when your stable prefix is long enough to matter and when your workflow avoids constant history growth. If you cannot measure prompt-token billing and cache hit rate, you will likely misjudge savings and overestimate the impact of caching.
For health-adjacent use cases, the risk profile also matters: caching can store prompt artifacts, so redaction and clear retention expectations should come before cost optimization.
Key Takeaways
- Prompt caching reduces prompt-side compute by reusing cached states for repeated prompt prefixes.
- Cache hits depend on prompt identity and formatting stability, not on semantic similarity.
- Measure savings using prompt-token metrics and latency, ideally with a controlled A/B test.
- Control history and retrieval placement so the stable prefix stays stable and long enough to matter.
- Verify caching retention and isolation rules; redact sensitive identifiers before caching when required.