MCP Servers In Plain Terms
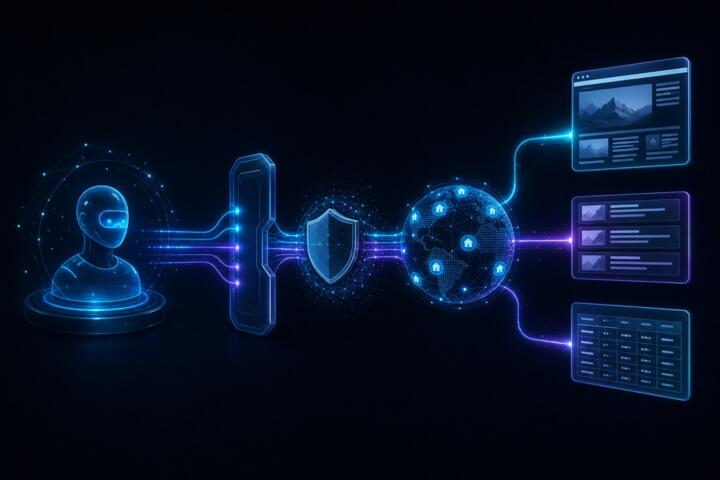
MCP stands for Model Context Protocol, a specification that lets an AI assistant talk to external “tools” and “data” through a consistent interface. Instead of hard-coding one integration per app, an MCP server exposes capabilities such as search, database queries, ticket creation, or document retrieval, and the assistant calls those capabilities using structured requests.
In practical terms, an MCP server acts like a controlled gateway. The assistant does not directly scrape your systems; it sends a tool call to the MCP server, and the server decides what it will fetch or change. If you have ever used a plugin system, MCP feels similar, but it focuses on a formal protocol for tool discovery and invocation, which matters when you want predictable behavior across different assistants.
Tool discovery is one of the key mechanics. The assistant can ask the MCP server what tools exist, what parameters each tool expects, and what the tool returns. That reduces the “guessing” layer that often breaks integrations, especially when the tool schema changes. I noticed this in a local setup where the server reported tool names and JSON schemas, and the assistant adapted without manual prompt rewriting—version numbers like “mcp-server v0.7.x” showed up in logs, which helped debugging.
Common Pain Points And Misreads
People often assume MCP servers automatically make access safe. The protocol standardizes communication, but it does not automatically enforce your organizational security policy. If the MCP server is configured with broad credentials, the assistant can still trigger actions that the organization did not intend.
Another frequent misread is treating tool schemas as “documentation.” A schema tells you parameter names and types, but it does not describe business rules such as rate limits, allowed data scopes, or whether a tool writes to production. A tool might accept a “recordId” parameter, yet still reject requests outside a tenant boundary, which leads to confusing failures that look like model errors.
Transport and runtime dependencies also cause surprises. MCP runs over a transport layer (often stdio for local processes or HTTP/WebSocket in hosted setups), and the assistant’s host application must support that transport. If the host app updates its MCP client behavior—say, a change around tool-call streaming in a release dated 2025-02—tool calls can fail even though the server still works.
Finally, many integrations break at the boundary between “read” and “write.” Retrieval tools that return documents are easier to reason about than mutation tools that create or modify records. When both exist on the same MCP server, you need clear separation of credentials and scopes, or the assistant will mix behaviors in ways that are hard to audit later.
How To Evaluate MCP Access
Start With A Threat Model
List the MCP server capabilities and classify each tool as read-only, write, or mixed. Then map each tool to the minimum credentials it needs. For example, a “search_documents” tool should use a read-only token, while a “create_ticket” tool should use a separate token with narrow permissions. If you cannot separate credentials, treat the server as high risk and restrict who can trigger tool calls.
In a typical audit, you also check whether the MCP server logs tool calls with parameters. Logging helps incident review, but it can leak sensitive fields if you log full request bodies. A mild frustration: many teams enable verbose logs during testing and forget to turn them down, which leaves personal data in log storage.
Test Tool Calls With Dry Runs
Before connecting an assistant to real systems, run the MCP server in a staging environment and test tool calls using a small set of known inputs. Aim for predictable outcomes: a read tool should return a stable document count, and a write tool should either be disabled or routed to a sandbox. If your MCP server supports a “dryRun” flag, use it; if it does not, create a sandbox endpoint and point the server to that endpoint.
Track success rates by tool. In many teams, a practical target is that basic read tools succeed in the 90%+ range under normal inputs, while write tools start lower until schemas and permissions are tuned. If a tool fails frequently, the assistant will keep retrying with slightly different arguments, which can amplify load on your systems.
When you test, verify that the assistant respects the tool schema. A tool expecting ISO-8601 dates should not receive free-text dates. I once saw a schema accept a string type, and the assistant passed “last Friday,” which the server rejected; tightening the schema to a date format reduced failures.
Constrain Data Scope And Output
Use server-side filters to limit what the assistant can retrieve. For example, enforce tenant scoping, document ACL checks, and maximum result sizes. If a tool returns full document text, add a server-side cap such as “top 5 passages” or “max 50KB per response.” Without caps, the assistant can ingest large payloads that increase latency and raise the chance of exposing sensitive content.
Also constrain what the assistant can do with outputs. If the assistant can call a “summarize” tool that writes back to a system, you need separate permissions for that write path. You save time, reduce noise, and the inbox stops winning—because fewer accidental write calls reach downstream workflows.
Plan For Observability And Rollback
Instrument the MCP server and the host application. At minimum, record tool name, request ID, execution time, and error codes. If you use HTTP transports, capture correlation IDs so you can trace a single assistant action across components. A practical aside: I’ve seen teams rely on timestamps alone, and then a clock skew of a few seconds makes incident timelines messy.
Keep a rollback plan. If a new tool schema version breaks calls, you want a way to pin the assistant to a compatible server version or to temporarily disable the tool. MCP tool discovery can make this easier because the assistant learns what tools exist, but you still need operational controls on the server side.
Educational Case Examples
Read-Only Knowledge Search
A support team sets up an MCP server that exposes a “search_kb” tool over an internal knowledge base. The server uses a read-only service account and enforces tenant scoping by customer ID. The assistant calls the tool with a query string and a “maxResults” parameter capped at 5. In testing, the team measures that most queries return within 800–1500 ms, while ambiguous queries return fewer results but still succeed.
When the assistant drafts responses, it cites only the passages returned by the tool. The team adds a rule that the assistant cannot call any write tools in this environment. The outcome is fewer hallucinated citations because the assistant’s context is limited to retrieved passages, and the server rejects requests outside the allowed customer scope.
Write Actions With Tight Scopes
A small operations group exposes a “create_change_request” tool through MCP. The tool writes to a ticketing system, but the MCP server uses a dedicated token restricted to a single project. The server requires a “changeType” parameter with an enumerated set and rejects unknown values. During staging tests, the team finds that 2 out of 20 tool calls fail due to missing required fields, which they fix by updating the tool schema and adding server-side validation messages.
In production, the assistant is allowed to call the write tool only after a human confirms the extracted fields. That confirmation step reduces accidental writes, and the server logs the final payload for audit. The team also sets a rate limit per user session to prevent repeated retries from creating duplicate tickets.
Comparison Checklist For Access
| Decision Point | Read-Only MCP Tools | Write MCP Tools | Mixed Servers |
|---|---|---|---|
| Credential Scope | Read-only tokens per tenant | Separate write tokens per project | Split credentials or split servers |
| Data Caps | Limit results and payload size | Validate fields and reject unknowns | Apply caps on both retrieval and outputs |
| Audit Trail | Log tool calls without sensitive payloads | Log final write payload and outcome | Ensure logs cover both read context and write actions |
| Human Control | Optional confirmation for sensitive queries | Recommended confirmation before writes | Mandatory confirmation for write paths |
Step-by-step checklist for a safe rollout: (1) enumerate tools and classify read vs write, (2) create separate tokens and scopes, (3) cap retrieval size and validate write parameters, (4) run staging tests with a small input set, (5) enable logging with redaction, (6) add rate limits and a rollback switch, (7) review one week of logs before expanding tool access.
Common Mistakes That Break Trust
Teams often expose a “general” tool that forwards arbitrary queries to internal systems. Even if the assistant cannot see raw credentials, a permissive query interface can still return data outside intended boundaries. Restrict query patterns to known filters, and enforce ACL checks server-side.
Another mistake is treating tool outputs as automatically correct. If a tool returns stale data, the assistant may draft confident text from outdated records. Add freshness checks where possible, such as “lastUpdated” fields, and make the assistant ask for clarification when the tool indicates low confidence or missing fields.
Schema drift also causes silent failures. When a server updates tool parameters, the assistant may keep calling old argument names until tool discovery refreshes. Pin versions during testing, and watch for errors like “unknown parameter” or “missing required field” that appear only after deployment.
Finally, promotional writing creeps into documentation. If your internal guide says “the assistant can access everything,” the team will stop verifying permissions. Replace vague claims with a list of tools, their scopes, and the exact environments where they are enabled.
FAQ
What Does An MCP Server Expose?
An MCP server exposes discoverable tools and data access endpoints through a standardized protocol so an AI assistant can call them with structured parameters and receive structured results.
Can An Assistant Bypass MCP Server Permissions?
The assistant cannot bypass server-side checks if the MCP server enforces access control. If the server is misconfigured with overly broad credentials, the assistant can still trigger actions within those credentials.
How Do Tool Schemas Affect Reliability?
Tool schemas define required parameters and types, which reduces guesswork. Reliability improves when schemas include strict validation rules and when the assistant host refreshes tool discovery after server updates.
What Risks Come From Write Tools?
Write tools can create or modify records, so risks include accidental changes, duplicate actions from retries, and audit gaps if logs omit payloads or redact too aggressively.
How Should I Test MCP Integrations Safely?
Use staging credentials, cap outputs, run a small test suite of tool calls, and route write actions to a sandbox or disable them until you confirm schema validation and permission boundaries.
Author's Insight
MCP servers standardize how assistants discover and call external tools, but they do not replace security engineering. The practical safety boundary sits in server-side authentication, authorization, data scoping, and validation of tool inputs and outputs. The most common failures show up at interfaces: schema drift, transport mismatches, and unclear separation between read and write capabilities. A careful rollout treats MCP as an integration layer that needs staging tests, logging with redaction, and rollback controls.
Key Takeaways
- MCP servers act as gateways for tool calls; the assistant’s access depends on server-side permissions and validation.
- Classify tools as read-only or write, then separate credentials and scopes to reduce accidental actions.
- Use staging tests with capped outputs and strict schema validation; track success rates per tool.
- Instrument the MCP server and host for auditability, and keep a rollback switch when schemas change.